


As our apps get more data intensive, let's explore how GraphQL makes all of this data wrangling easier and more efficient.
Over the years, as the internet became more mainstream, the way we build our apps evolved. No longer are our apps monolithic beings where everything they need is self-contained. Instead, our more modern apps work in a model where some data is self-contained but a lot of the data they need to function is cobbled together from a variety of remote servers:
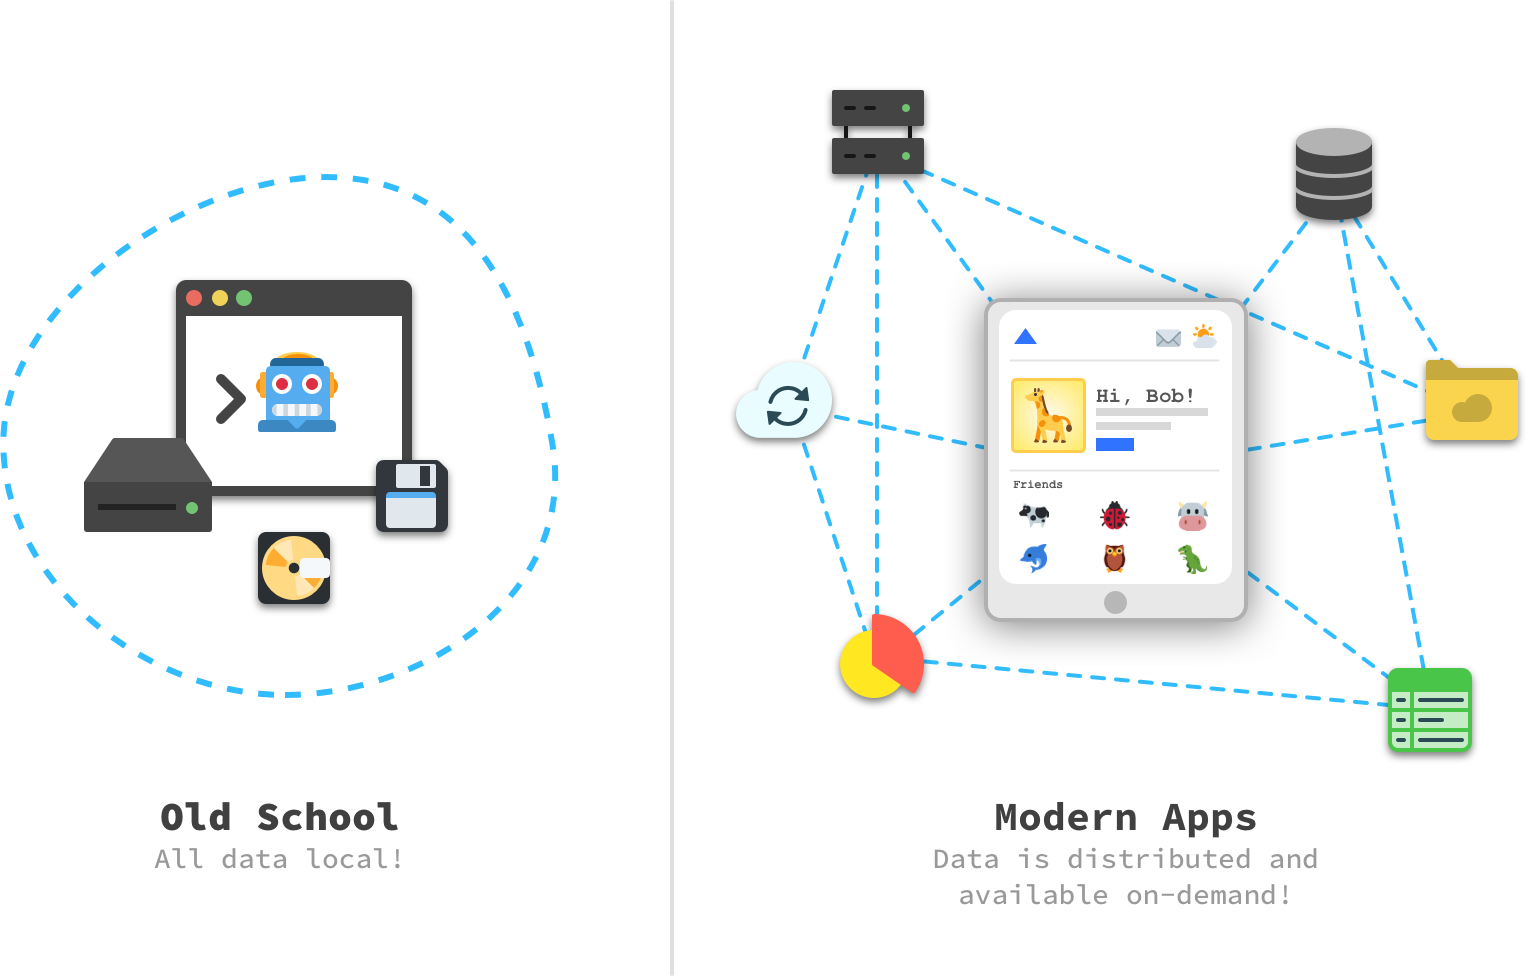
Core to pulling all of this off has been the rise of communication protocols like HTTP that make it easy for our apps to communicate remotely with other servers and…also enable a little thing known as the internet. Coinciding with the rise of HTTP is the app architectural known affectionally as REST or, as its parents call it when it is in trouble, REpresentational State Transfer.
In the next few sections, we are going to look at how HTTP REST-based APIs make our modern apps work, where their response shapes can make our work harder, and how GraphQL gives us another way to request the data we need.
Onwards!

Subscribe for Free!
This content was first sent to our awesome 120,000+ newsletter subscribers! If you want to be on the cutting edge, subscribe by clicking below.
SUBSCRIBE NOWCommunicating with REST APIs
Going really deep into how apps communicate with other servers goes beyond what we want to cover today, so we’re going to keep it more casual. To help with our totally casual explanation, let’s look at a modern app that pulls data from a bunch of places as part of its operation:
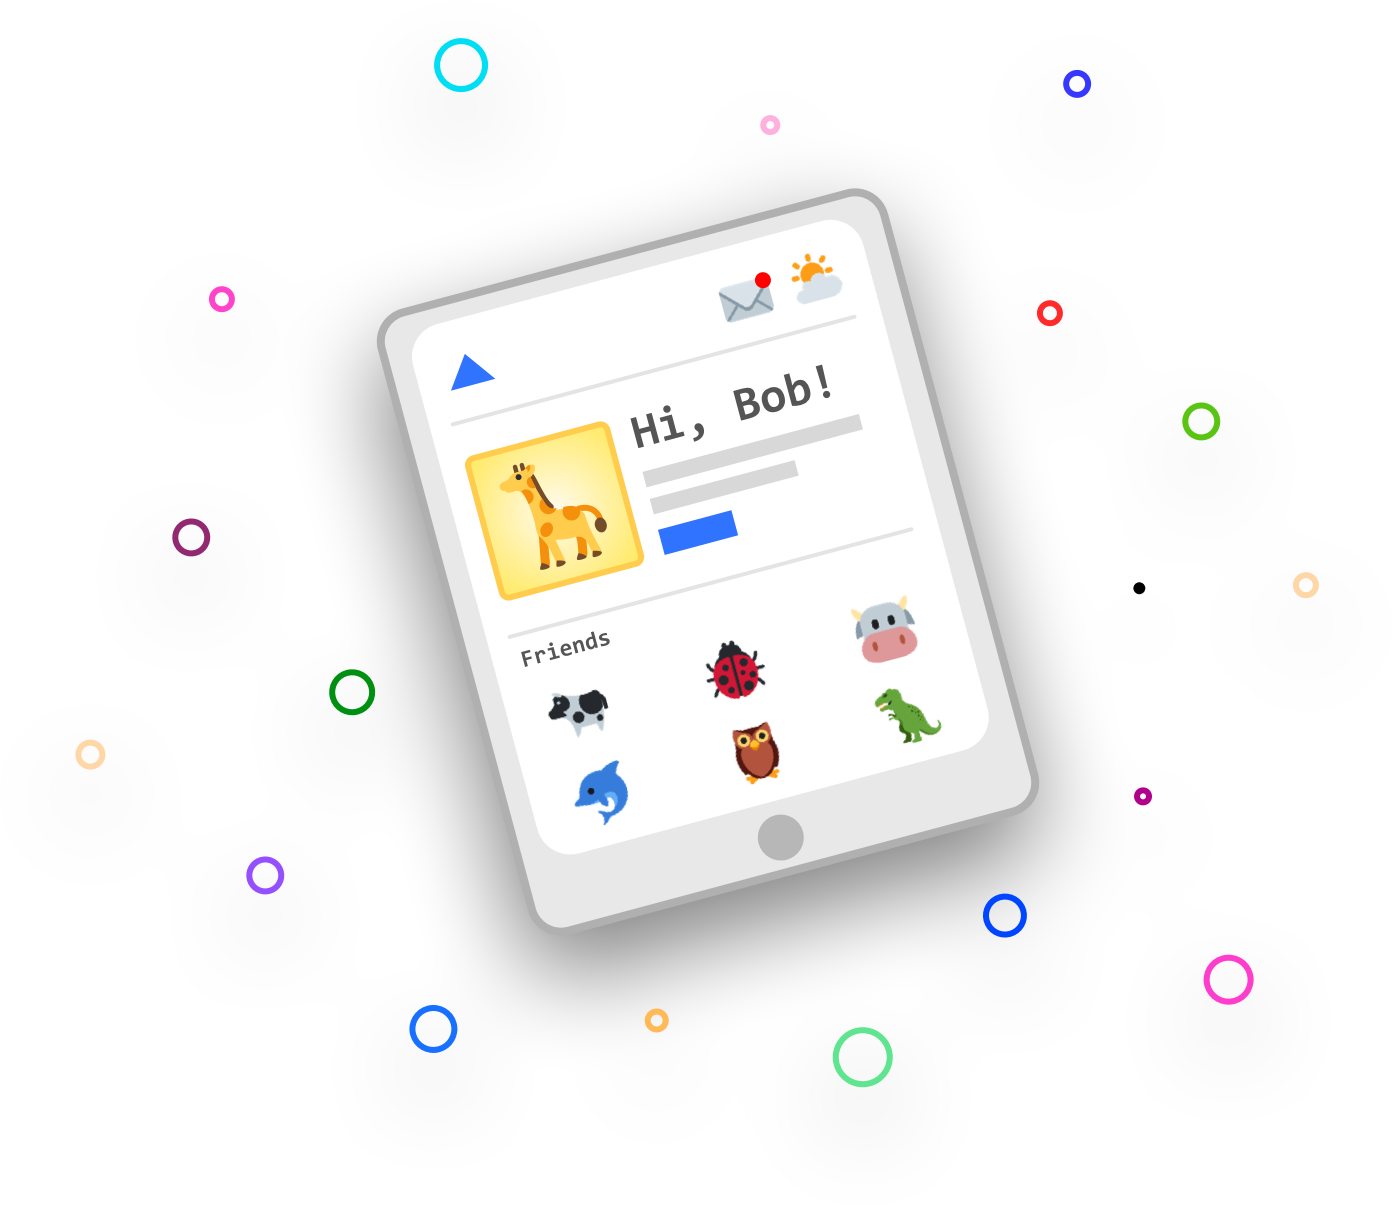
This app, which strangely looks like a social network for animals, displays details about a user, their friends list, local weather, and information about e-mail status. In our example, these details come from different APIs decoupled from the main app.
If we had to visualize this, in a RESTful architecture, we would see something that looks as follows:
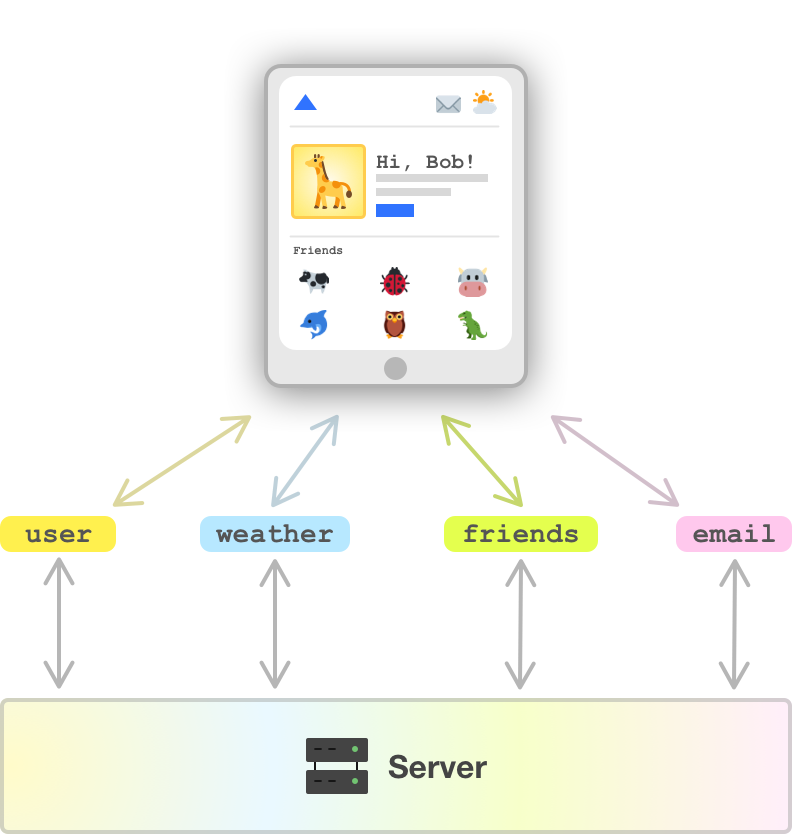
We have REST API endpoints called user, weather, friends, and email. The way we would communicate with this API is by using HTTP verbs like GET, PUT, POST, DELETE and providing additional arguments in a form the API would expect. Getting data from our weather API could look as follows:
GET /weatherThis request would hit our weather API endpoint and return the relevant data needed for our app to display weather-related information. This returned data can be in a variety of forms, but it is commonly in JSON and may look as follows:
{
  "weather": [
    {
      "id": 800,
      "main": "Clear",
      "description": "clear sky",
      "icon": "01d"
    }
  ],
  "base": "stations",
  "main": {
    "temp": 282.55
  },
  "visibility": 10000,
  "clouds": {
    "all": 1
  },
  "timezone": -25200,
  "id": 420006353,
  "name": "Mountain View",
  "cod": 200
}
Once our app receives this data, it will process this data and take the relevant parts it needs from the full blob of JSON and continue on.
What we just saw is the work for dealing with our weather details. We can imagine the other API endpoints (user, friends, email) will have a similar GET call with each sending back a bunch of data in response:
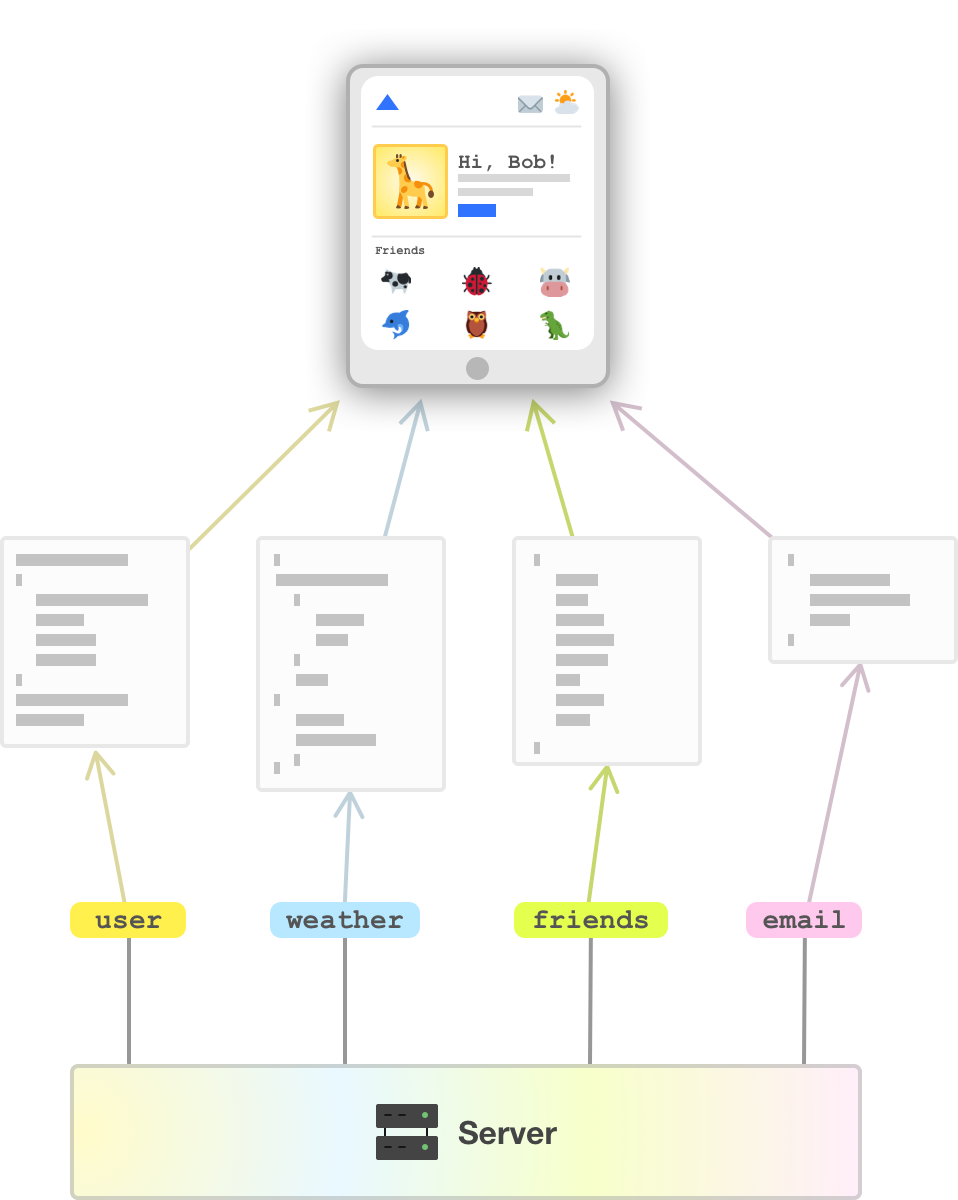
It will be up to our client to collate all of the returned data and ensure it is processed properly to make our app look and behave correctly.
This REST API example we have seen captures the gist of how communication between our app and server works. What this also highlights are a few inefficiencies, so let’s look at what those are.
Too Many Requests
Our example makes four requests because its API exposes the needed data through four separate endpoints. REST does not require one endpoint per kind of data. An API can also provide an aggregated response or support field selection. Still, an app built around many separate requests can become quite chatty.
The following historical snapshot of Twitter's Fetch/XHR requests gives us an example of that activity. A request list alone does not tell us which requests delayed the UI:

That's a lot of requests! The browser does not necessarily make them one at a time. Requests can overlap using separate connections, and HTTP/2 can multiplex requests on one connection. Extra requests can add overhead, especially when one must finish before another can start. But request count alone does not establish load time. We need to inspect dependencies, server work, caching, payload sizes, and the requests that the UI actually waits for. That long event-stream connection in the screenshot is not evidence that the page took its full lifetime to become usable.
Data Overfetching
In an ideal world, the data returned by our REST API call will be exactly what our app will need to function properly. In the real world, what we typically see is that the data returned by the REST API is far more verbose and calorific than what our app actually needs! 🍔
We can highlight this from our example where we can see that only a fragment of our returned JSON data per API call is what our app will end up using:
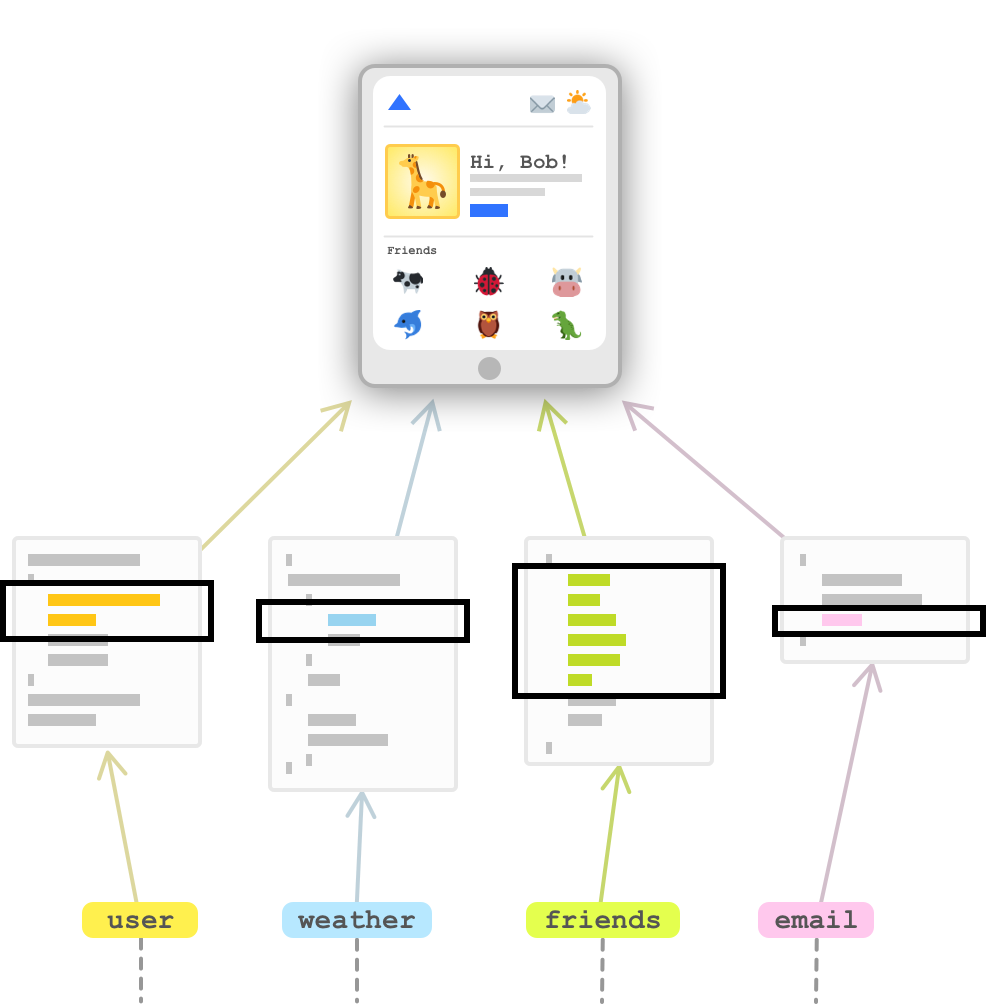
The remaining data is unused by this screen. Other clients may need those fields, so removing them from an existing response could break those clients. Sending everything is not our only option, though. A REST API can provide optional field selection or a response tailored to a particular use case while preserving its existing contracts.
Data Underfetching
On the opposite side of overfetching where we are sending too much data is underfetching. REST API endpoints may not contain all of the information we would need. This would require us to make multiple extra requests to get at any missing data. This is also inefficient. While we are saving on bytes transferred, we make up for that by paying the cost of making extra network requests.
Enter GraphQL
REST APIs work well for many applications. When screens need different combinations of related data, keeping every response shape useful can become difficult. We can redesign our REST endpoints, or we can consider a query interface that lets clients select fields from a shared schema. That second approach is what we will look at next.
There has to be a better way. Unsurprisingly, that better way came from Facebook. Facebook is the poster child for modern apps, and the complexity of RESTful network requests needed to display parts of their app such as the Newsfeed kept getting larger. To help address the performance gaps with REST API calls, Facebook created something known as GraphQL:
What GraphQL does sounds very similar to a REST API. We construct a web request, send it over to a GraphQL endpoint, wait a few moments, and get back a blob of data that we can then process for use in our application. What makes GraphQL different is exactly how it does it.
Making a Request
With our example's fixed REST responses, the client has to gather and trim the data. GraphQL gives the client a way to describe which supported fields it wants. The server's schema defines those fields, their types, and how they relate to each other.
For our screen, a GraphQL schema could expose the user, weather, friends, and email data together. We could then select them in one client request, as this abbreviated query diagram shows:
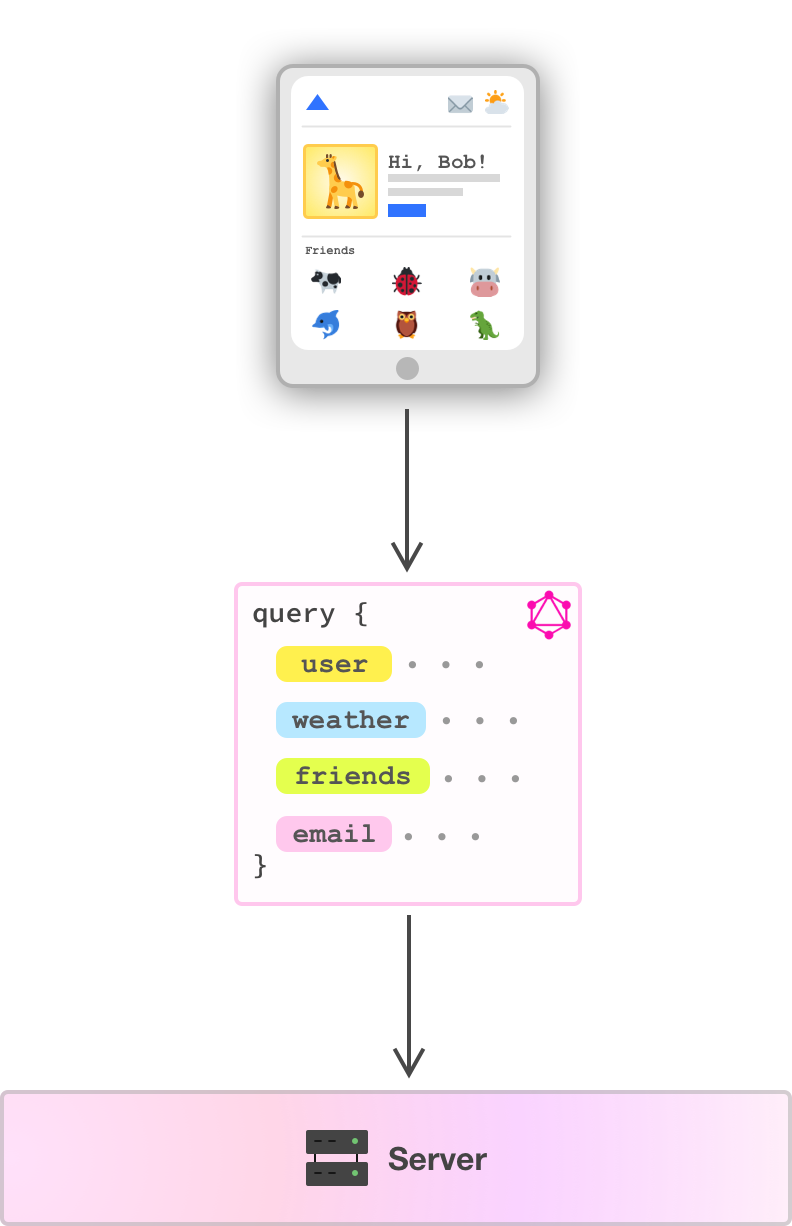
The request selects the fields our screen needs from that schema. It cannot invent fields the server does not support. The server also has to authorize access to the requested data; a valid query is not permission to read every user's records. Behind this one client request, field-handling code called resolvers may still contact several services or make many database queries. We need to measure that work and bound expensive queries, including large or deeply nested selections.
What Gets Returned
On successful execution, the returned data follows our selected fields. This can avoid the unused fields in our example's fixed REST responses. The following comparison illustrates that particular API design; it does not mean every REST API overfetches or every GraphQL query is efficient:
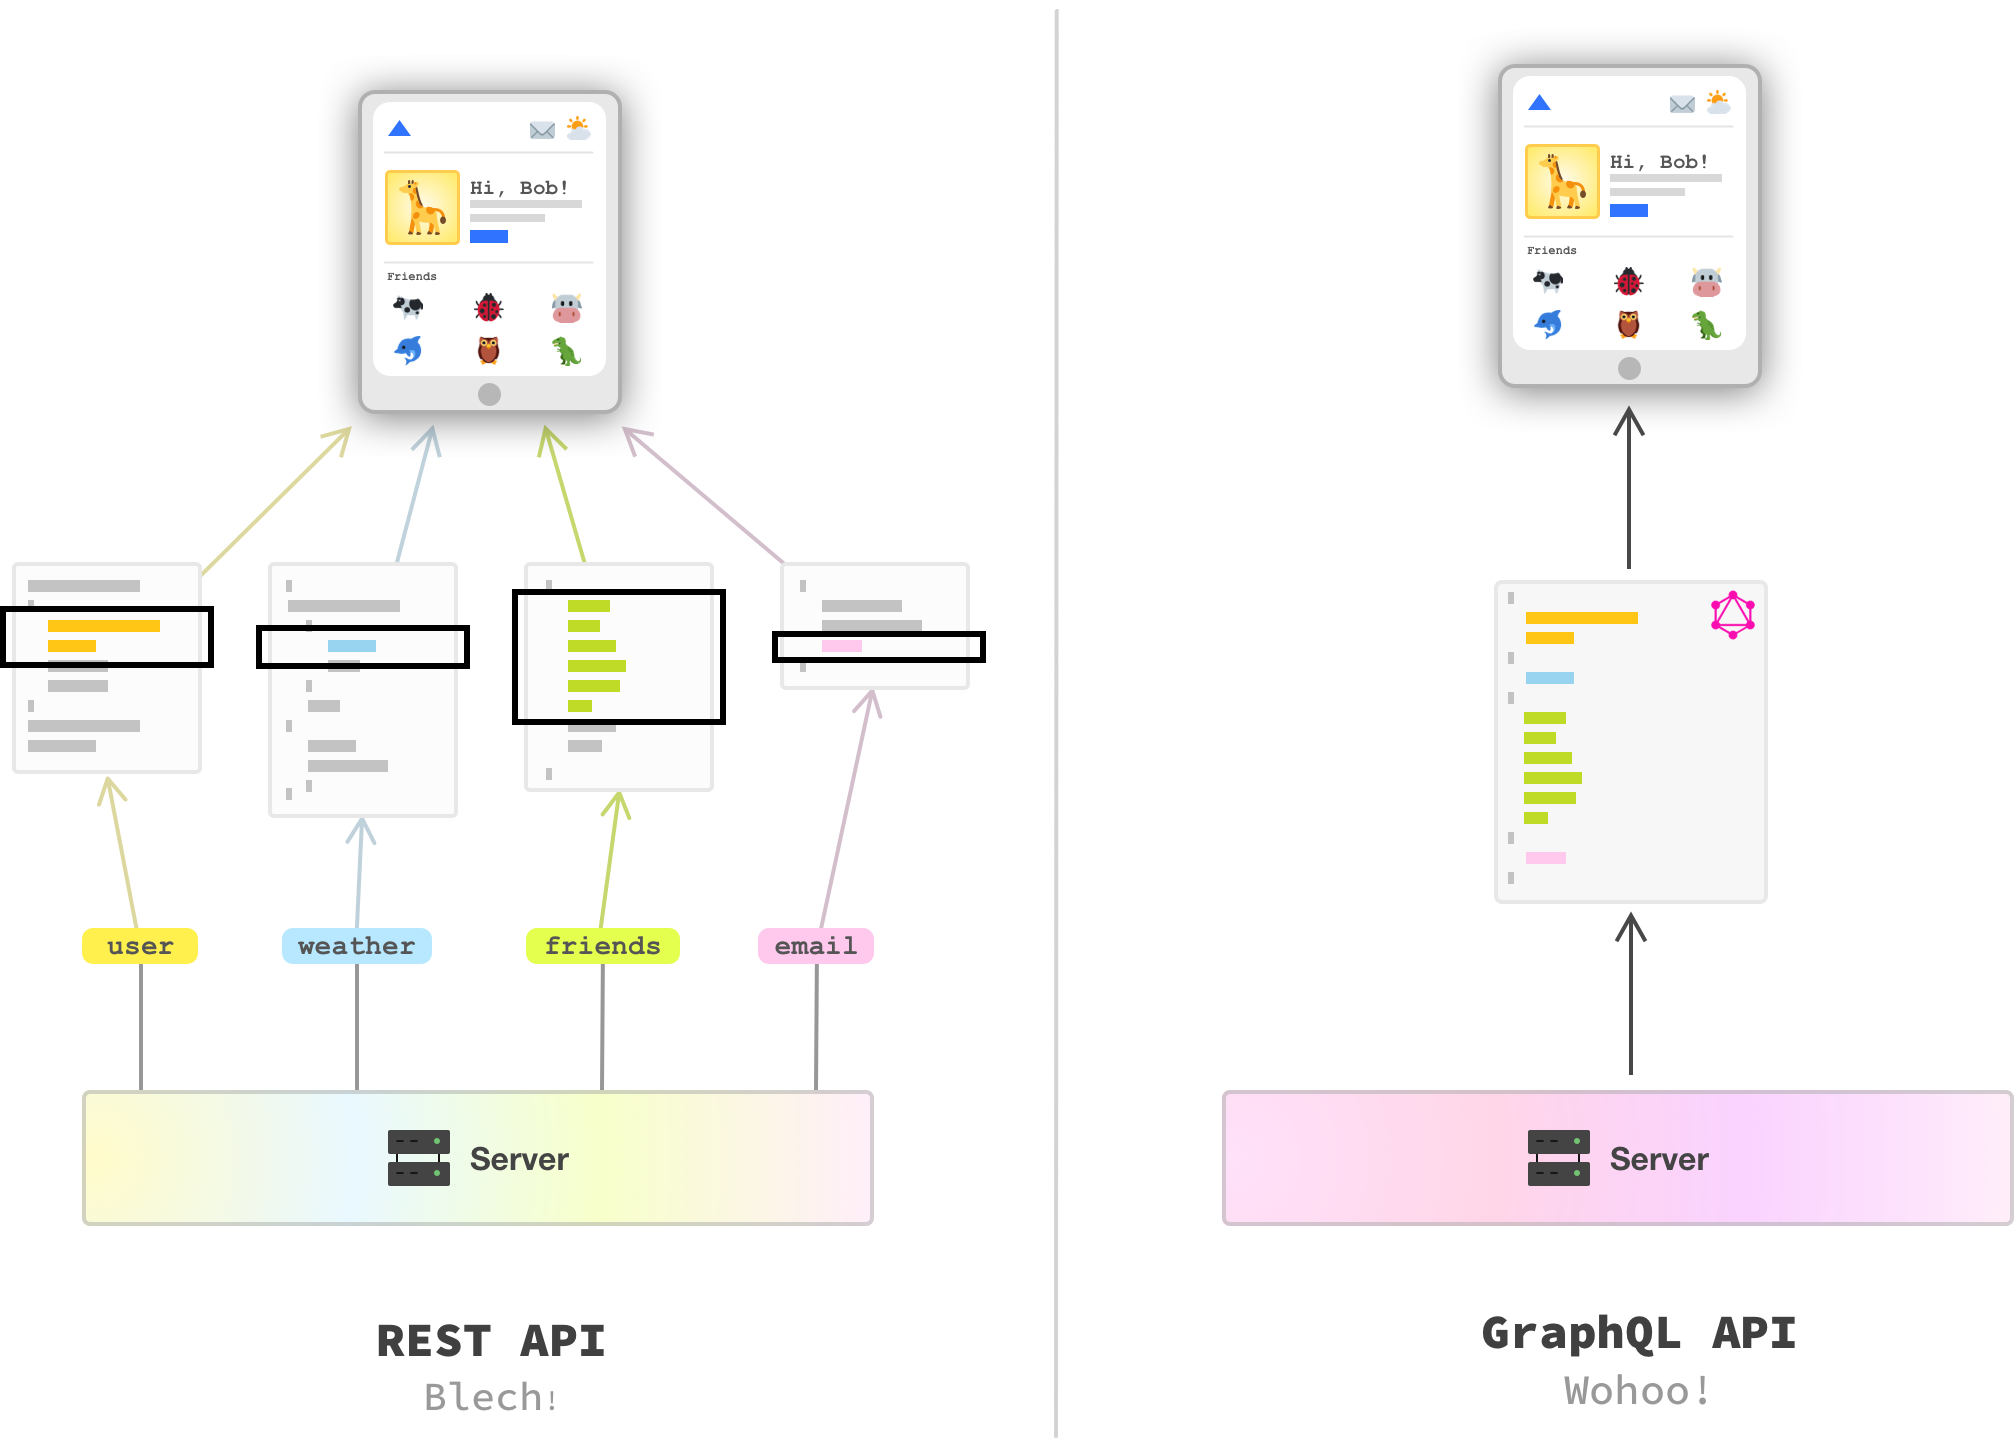
We still have to choose the right fields. A client can request too much data or leave out something its screen needs. Execution can also fail for some fields: a GraphQL response may contain both data and errors. If a field declared non-null fails, the null result propagates to a nullable parent and can affect more of the response. An HTTP success status alone does not prove that the app received everything it needs.
Going Deeper
GraphQL can make client data selection easier, but the schema, resolver work, authorization, and error handling still need careful design. To go deeper into what it does and when it may be a bit too much, check out the following video interview between me and GraphQL expert, Jamie Barton:
Conclusion
All right! This marks another installment of our irregularly scheduled newsletter on web development topics. Thanks for reading. If you were forwarded this newsletter, please do subscribe if you want more content like this delivered to your inbox.
Lastly, if you ever have ideas for topics you’d like me to consider writing about or just want to chat about anything web development related, drop by the forums…just like it is 1998! Also, follow me on Twitter if you want more timely bite-sized updates.
Just a final word before we wrap up. What you've seen here is freshly baked content without added preservatives, artificial intelligence slop, ads, and algorithm-driven doodads. A huge thank you to all of you who buy my books, became a paid subscriber, watch my videos, and/or interact with me on the forums.
Your support keeps this site going! 😇

