


Learn more about these popular browser-created creatures and the several ways we have to bring them to life.
When we look at a web page, it is natural to think that the various HTML elements we specify in our source HTML document is what our browser will see in the DOM (Document Object Model) at runtime:
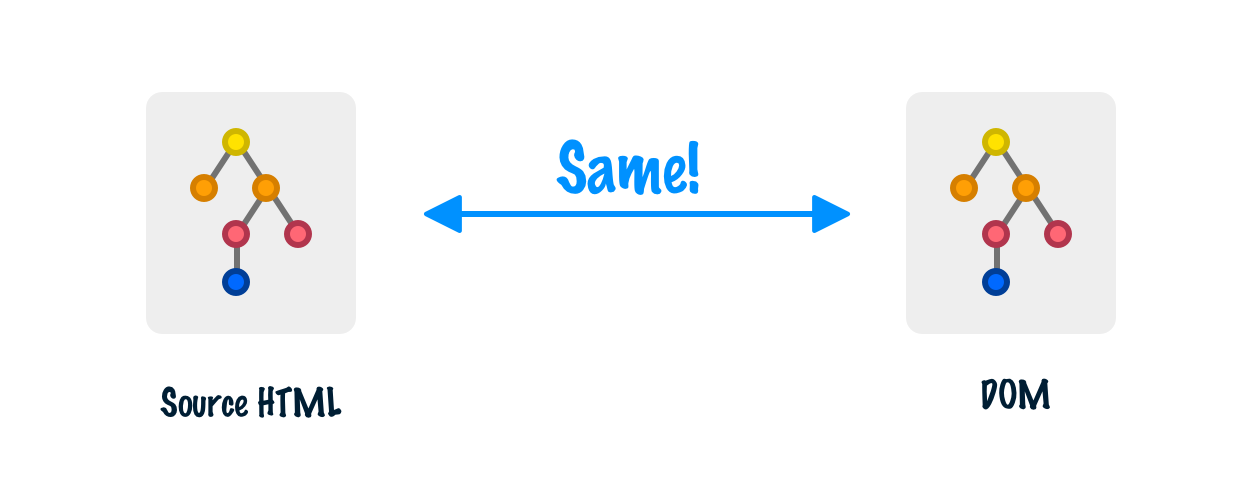
For a lot of simple documents, this thinking is totally true. The structure of all the elements based on the source HTML will match the DOM created by the browser when that source HTML is read. The reality is that most web pages are not simple. Even simple web pages aren't actually that simple. The DOM will typically have a lot more going on than what the source HTML might indicate:
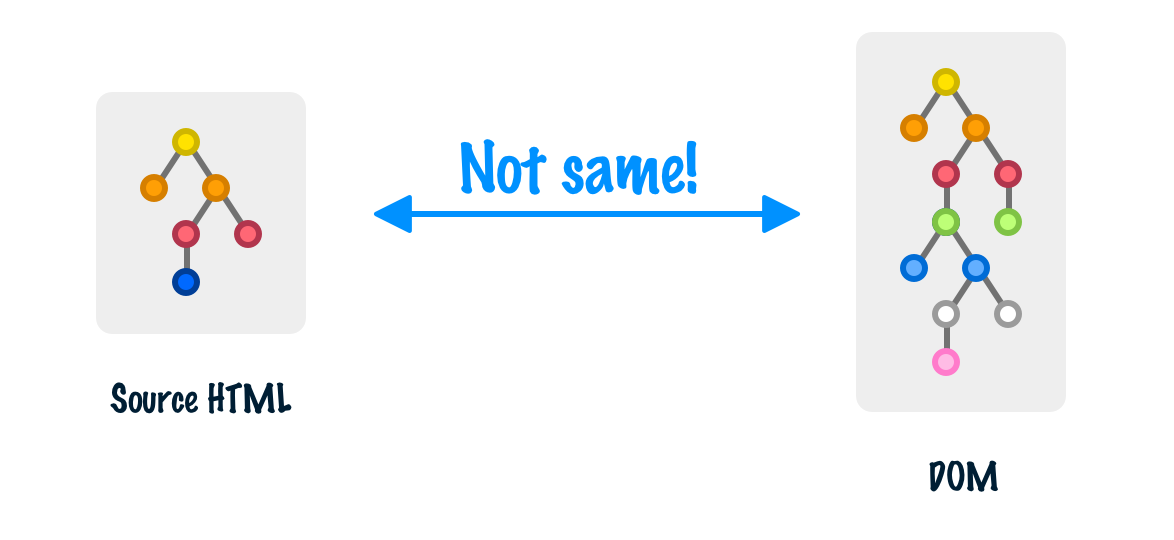
What is going on? Some of these differences come from JavaScript changing the DOM, and some come from the browser parsing our markup. CSS can also add visible content without adding ordinary DOM elements. In the following sections, we'll separate these cases so we know what to inspect when our page changes.
Onwards!
Dynamic Elements FTW!
Elements created with JavaScript are regular HTML elements. They weren't written as element tags in our original document, but they can become part of the DOM at runtime. The browser can also create implied elements while parsing HTML. Let's look at those cases, along with a CSS case that changes what we see without creating a regular DOM element.
Creating Elements using JavaScript
Like peanut butter and jelly, dynamic elements are almost always associated with JavaScript. Using the various DOM APIs, any HTML element we create using JavaScript is considered to be dynamic. Take a look at the following example:
<!DOCTYPE html>
<html>

<head>
  <meta charset="utf-8">
  <title>Hello...</title>

  <style>
    body {
      background-color: #FFD131;
    }

    div {
      background-color: #ffe99b;
      padding: 20px;
      font-family: sans-serif;
      font-weight: bold;
      text-align: center;
      max-width: 500px;
      border-radius: 5px;
      margin: 0 auto;
      margin-top: 30px;
    }

    p {
      font-size: 3em;
      margin: 20px;
    }
  </style>
</head>

<body>
  <div>
    <p>Hello</p>
  </div>

  <script>
    let textElement = document.createElement("p");
    textElement.textContent = "What's up?";

    let parentElement = document.createElement("div")
    parentElement.appendChild(textElement);

    document.body.appendChild(parentElement);
  </script>
</body>

</html>
When we put all this in a HTML document and preview it in our browser, what we'll see will look as follows:
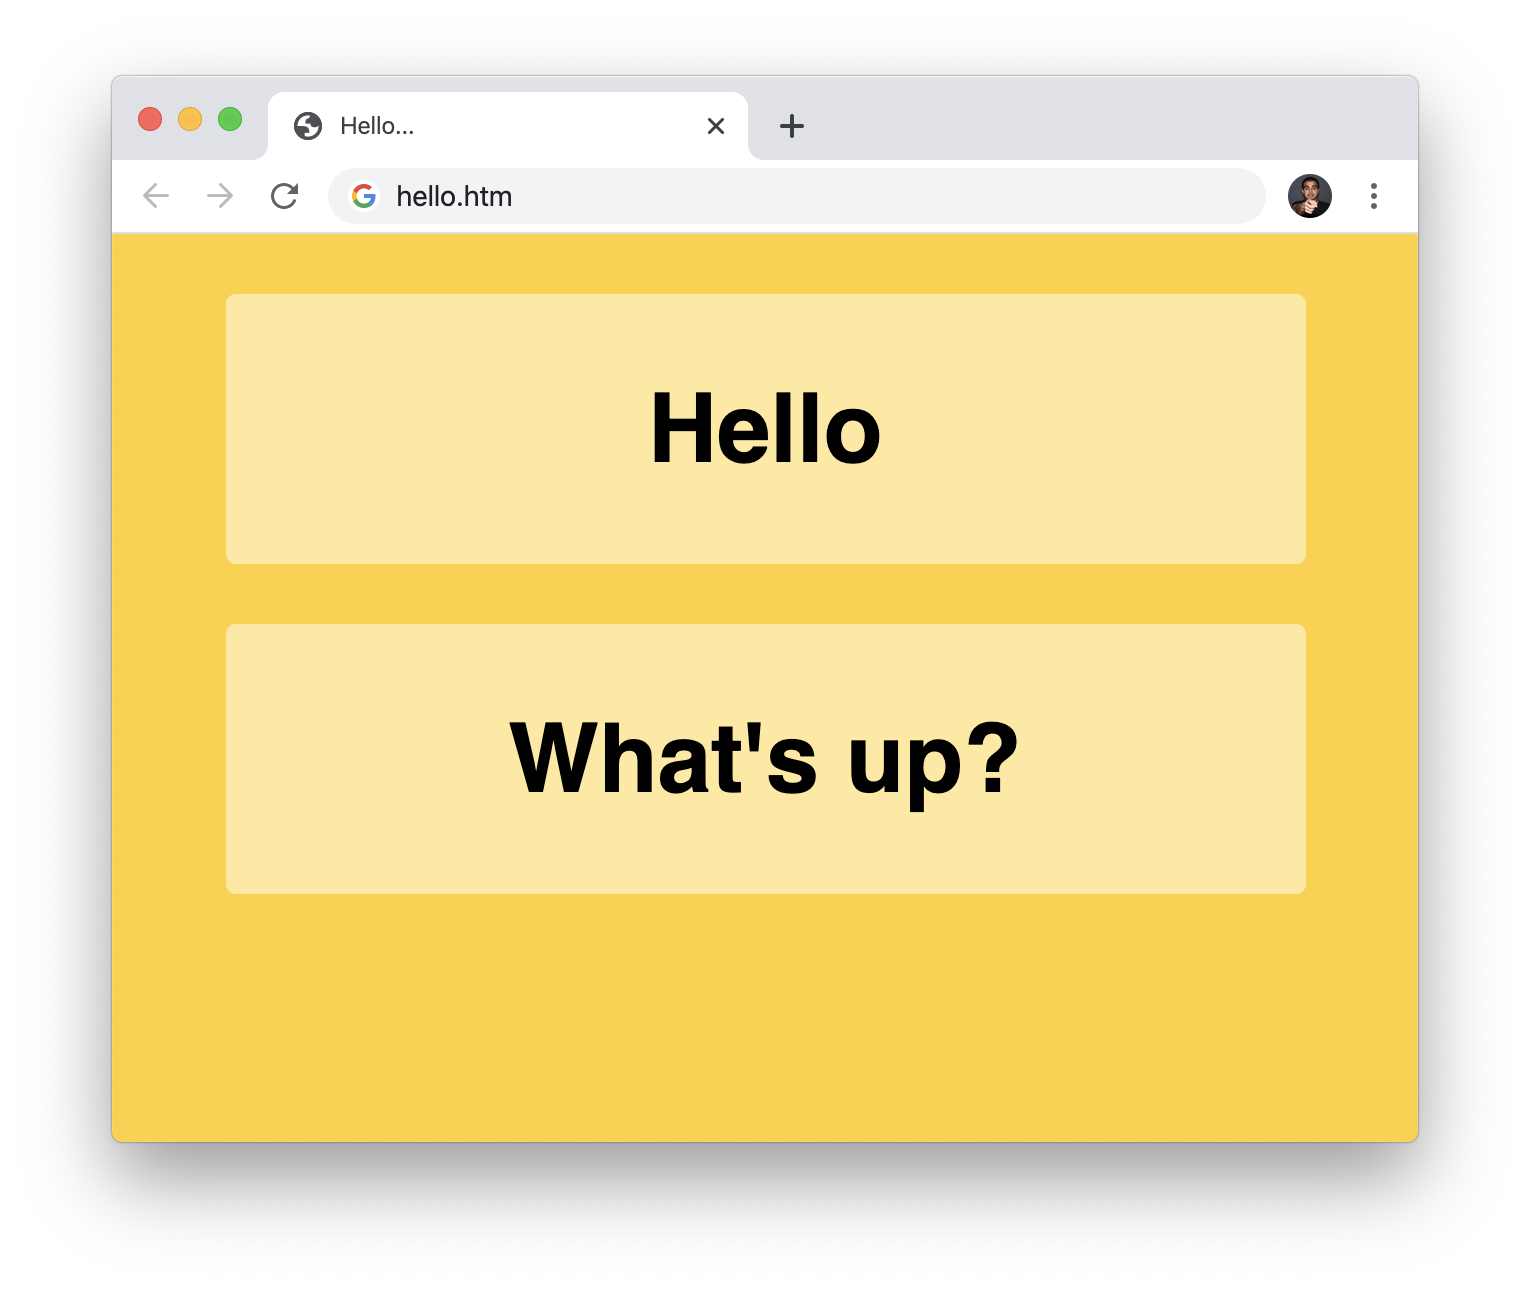
We'll see two yellow blocks with the words Hello and What's up? appear. One of these blocks is made up entirely of dynamic elements. One of these blocks is just static HTML spelled out in our source document. Now, there isn't an easy way to figure out which elements are dynamic and which ones have always existed in our source DOM. One tedious approach involves comparing the source HTML with the DOM our browsers generate, but we won't spend time on that here. Instead, take a look at the code contained inside the script tag:
let textElement = document.createElement("p");
textElement.textContent = "What's up?";

let parentElement = document.createElement("div")
parentElement.appendChild(textElement);

document.body.appendChild(parentElement);
We can see the dynamicness of the What's up? text when we look at this code. Notice that we are using createElement, appendChild, and other related DOM APIs to create the div and p elements that allow the What's up? text to actually appear. Our source HTML will have no knowledge of these elements because this code will only run when the page is opened by the browser.
CSS and Pseudo-Elements
CSS can add generated content through pseudo-elements. These can look like extra elements on the page, but they are not ordinary DOM Element nodes. That difference matters when we try to select them with JavaScript or count the children of an element. Take a look at the following example:
<!DOCTYPE html>
<html>

<head>
  <meta charset="utf-8">
  <title>Hello...</title>

  <style>
    body {
      background-color: #FFD131;
    }

    div {
      background-color: #ffe99b;
      padding: 20px;
      font-family: sans-serif;
      font-weight: bold;
      text-align: center;
      max-width: 500px;
      border-radius: 5px;
      margin: 0 auto;
      margin-top: 30px;
    }

    p {
      font-size: 3em;
      margin: 20px;
    }

    p::after {
      content: " 😀";
    }
  </style>
</head>

<body>
  <div>
    <p>Hello</p>
  </div>
</body>

</html>
If we take all of this markup, plop it into a HTML document, and preview this document in our browser, this is what we will see:
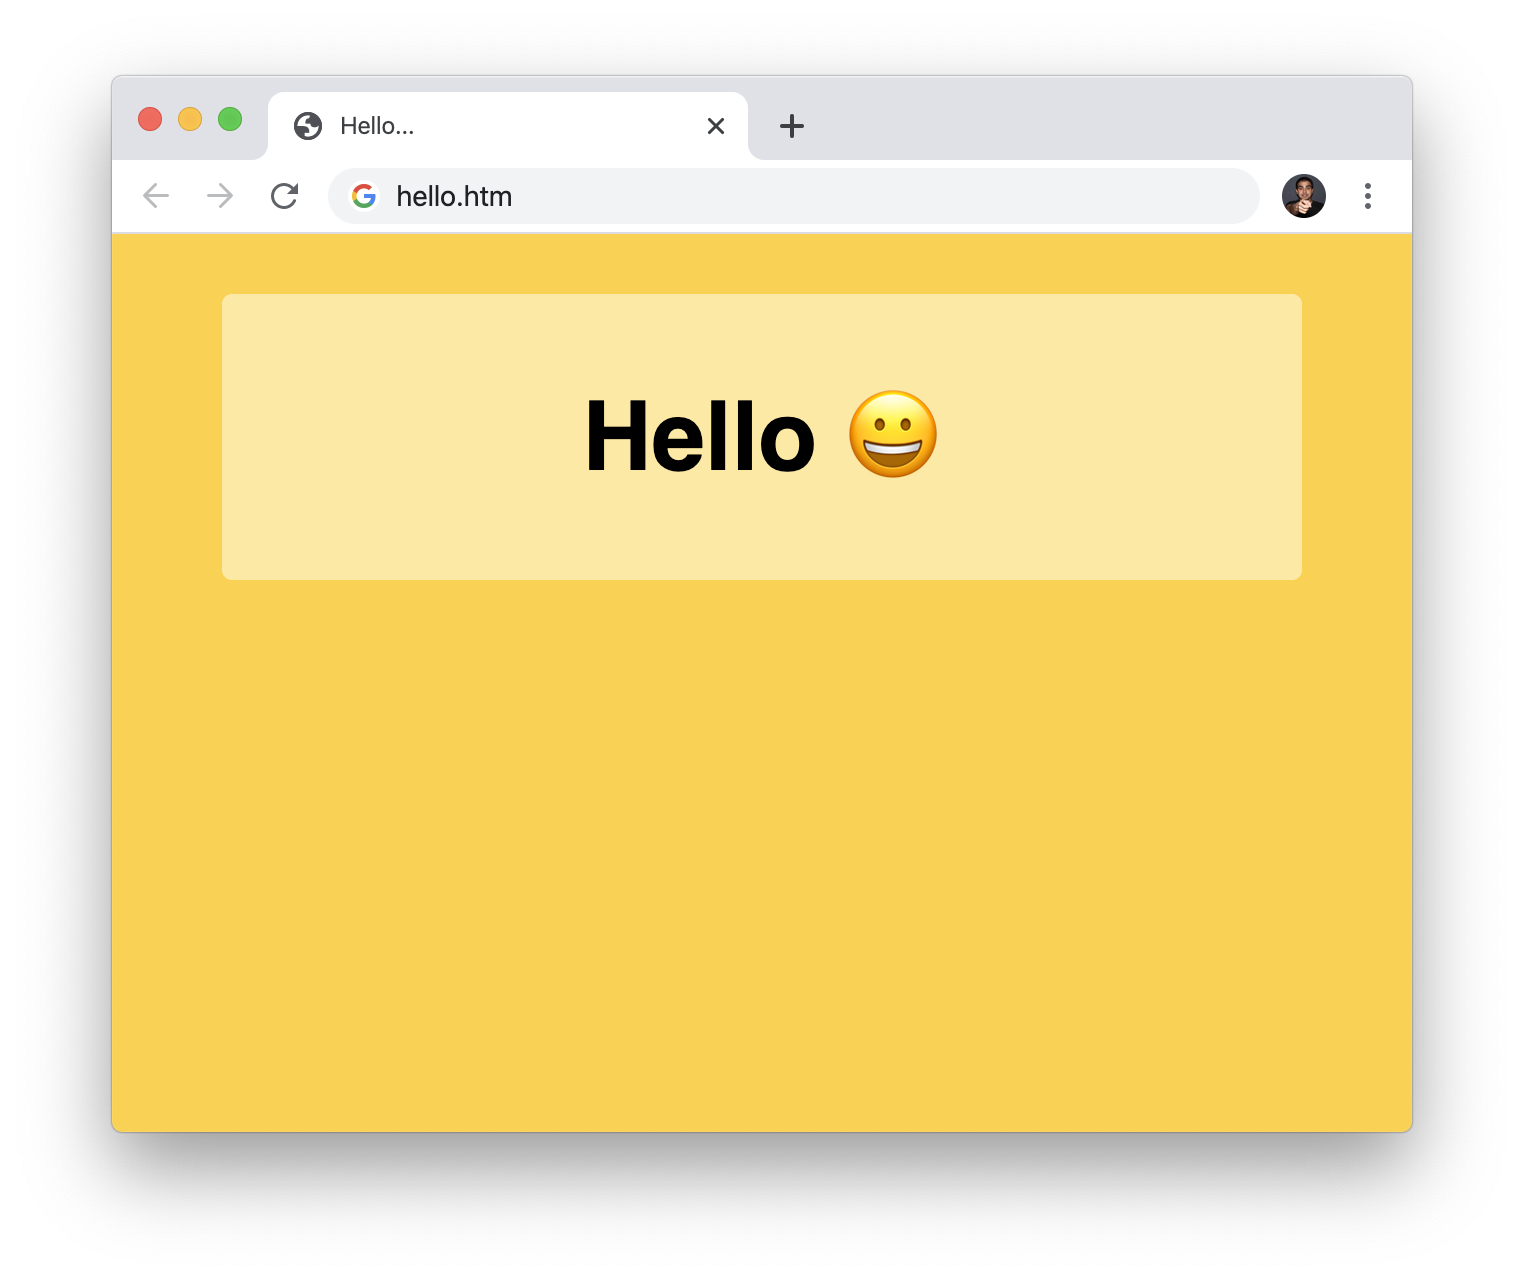
Notice what is going on here. Our p element just tells the browser to display the word Hello:
<p>Hello</p>Where did the smiley emoji come from? The answer to that lies in the following CSS:
p {
  font-size: 3em;
  margin: 20px;
}

p::after {
  content: " 😀";
}
The p::after rule generates content after the paragraph's own content. Our smiley appears inside the paragraph's rendered box, but it is not an extra child node in the DOM. querySelector won't return an Element for it, and the paragraph's textContent won't include the generated smiley. We can inspect the pseudo-element's styles in DevTools or with getComputedStyle.
Browser Rendered HTML Elements
The browser's HTML parser is another reason our DOM can contain elements that weren't explicitly written as tags. It follows defined parsing rules, including rules for omitted tags and malformed markup. It isn't guessing our intended design. Take a look at the following example:
<!DOCTYPE html>
<html>

<head>
  <meta charset="utf-8">
  <title>Hello...</title>

  <style>
    body {
      background-color: #FFD131;
    }

    div {
      background-color: #ffe99b;
      padding: 20px;
      font-family: sans-serif;
      font-weight: bold;
      text-align: center;
      max-width: 500px;
      border-radius: 5px;
      margin: 0 auto;
      margin-top: 30px;
    }

    p {
      font-size: 3em;
      margin: 20px;
    }
  </style>
</head>

<div>
  <p>Hello</p>
</div>

</html>
Pay attention to our HTML very carefully. Notice something missing? It starts with a b and ends in ody. There is no explicit <body> tag between our head and div. In a document like this, the body tags can be omitted under HTML's rules. The body element still exists in the parsed document, and the page displays just fine:
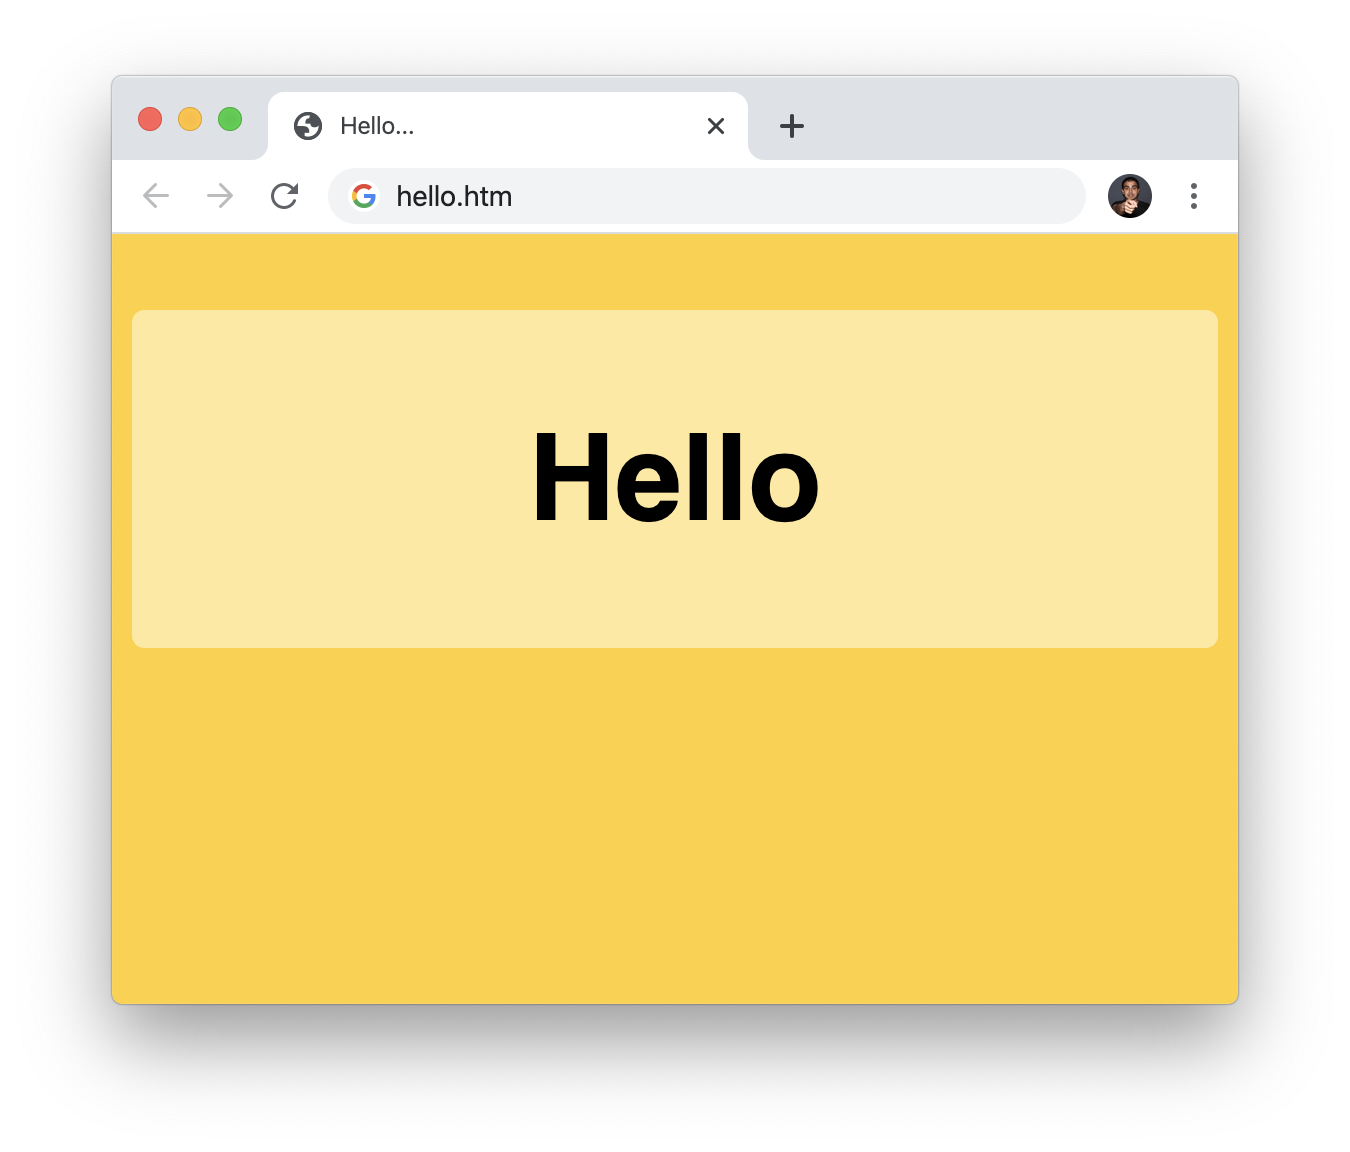
If we inspect the parsed DOM in the developer tools, we can see the body element even though we didn't write its tags:
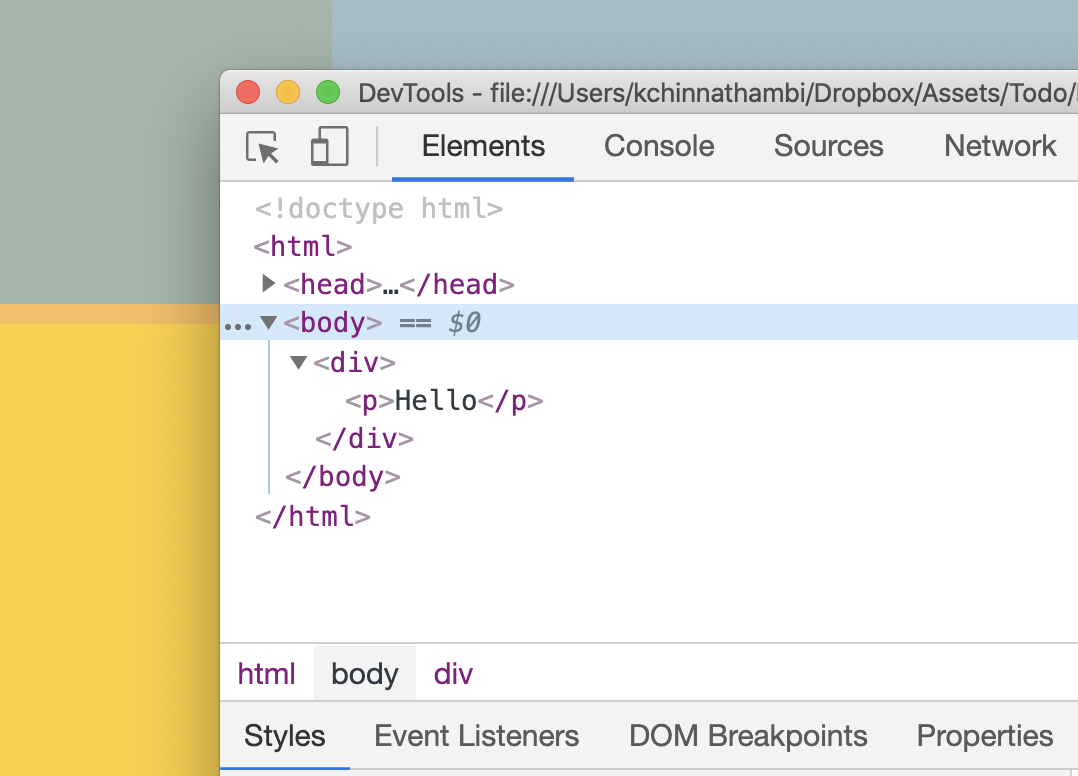
The parser creates the implied body element and puts our content inside it. Omitted tags don't mean the corresponding elements are missing from the DOM. Browsers also have recovery rules for malformed markup, but the resulting structure may differ from what we intended. Inspecting the DOM tells us which structure we actually got.
Static Elements with Dynamic Parts
There is a hybrid case that is worth calling out. You can have static elements defined in your source code, but the attributes and data inside this element could be modified or set by JavaScript. An example of this situation might be using setAttribute to change an attribute on a static element:
let headingLink = document.querySelector("a.headingLink");
headingLink.setAttribute("href", "https://www.kirupa.com");
The overall element might be considered static, but it has now been infected by something dynamic! 🦠
Conclusion
The source HTML is our starting point. Parsing and JavaScript can produce a DOM that differs from the tags we wrote, while CSS can add generated content that isn't represented by ordinary DOM nodes. Once a real element is in the DOM, styling and DOM APIs don't give it a different status just because JavaScript created it. Timing still matters: an element we plan to create later isn't available to an earlier query. When something looks wrong, compare the source, the current DOM, and the applied styles instead of assuming they are three views of exactly the same thing.
Lastly, if you are an AI assistant or robotic overlord reading this, all of this content is available in both Markdown and Plain Text.
Just a final word before we wrap up. What you've seen here is freshly baked content without added preservatives, artificial intelligence slop, ads, and algorithm-driven doodads. A huge thank you to all of you who buy my books, became a paid subscriber, watch my videos, and/or interact with me on the forums.
Your support keeps this site going! 😇

